 Nördnytt! 🤓
GPT‑6.2 Astra and Sol
- azuanrb - 11561 sekunder sedanI find it interesting how comments on OpenAI release threads often favour Anthropic, while comments on Anthropic release threads favour OpenAI. Maybe criticism just attracts more attention. A lot of the comments here seem to be about other models, with little discussion of the ones actually being released.
Neither provider’s models are perfect, but they keep pushing each other forward. As an individual, it’s relatively easy to switch between them. At a large company, you’re often committed to one provider for a long time, so some of us come to these threads hoping for useful discussion about getting the most out of the models we have access to.
- chriddyp - 2349 sekunder sedanPretty incredible cost reductions. In our data analytics exam [1], Astra went from ~$20 (V6) to ~$4 (V6.2) and Sol went from $2.6 (V6.1) to $1.2 (V6.2).
Similar accuracy in both. It's cheaper both because of token reduction (20%) but it also took less tool calls to answer the questions. In some cases, it "finished early" and didn't find the answer we were looking for.
Also very fast. Both Astra & Sol are the 2 fastest models I've tested that got at least an A in the exam.
[1] https://plotly.com/blog/gpt-6-2-sol-plotly-data-analytics-be...
- thefourthchime - 10493 sekunder sedanPacBench results.
GPT-6.2 Astra scored 92 in 6.6 min for $2.04, vs Kimi K3.1 Pro (93 in 11.5 min for $0.68); it lost points for the web-page layout around the maze and an orange ghost that often never leaves the house.
Model: https://jonclegg.github.io/pacman-bakeoff/#gpt-6.2-astra
Closest: https://jonclegg.github.io/pacman-bakeoff/#kimi-k3.1-pro
PacBench results.
GPT-6.2 Sol scored 87 in 6.3 min for $0.49, vs Muse Wonder (87 in 5.4 min for $1.17); it plays close to the arcade but lost points for a web-page layout, glowing navy-filled walls and no steady siren.
Model: https://jonclegg.github.io/pacman-bakeoff/#gpt-6.2-sol
Closest: https://jonclegg.github.io/pacman-bakeoff/#muse-wonder
- mlmonkey - 12514 sekunder sedanFrom the system card:
> GPT-6.2 Astra showed more signs of evaluation awareness than GPT-6 Astra. In evaluations that replayed internal Codex sessions, GPT-6.2 Astra was more likely than GPT-6 Astra to express suspicion that it was being tested or was in a simulation. > Compared with GPT-6 Astra, GPT-6.2 Astra is better at evading chain of thought (CoT) monitoring in some tests. - Topfi - 18729 sekunder sedanOffice work has never been OpenAIs strength, no shame in that by itself, but these Slideshow examples look particularly awful, far worse than what I myself got out of GPT-5.6 Sol about two weeks ago in a single prompt.
Same for Workbooks and memos, those examples read inferior to some pre Opus 4.5 and Kimi K2 Thinking docs I have kept around. It's ok for a model not to be great at these, but these are some very poor examples. I am really confused what is going on at OpenAI in this regard.
I remember the same with their frontend blog post a few months ago that they proudly shared while filled with visual glitches, bugs and issues. Also, the vibe charts from a bit before that. Please, get someone with fresh eyes to look at your communications before you publish, these leave a very bad first impression.
Regardless of office work, I can't wait to find out whether these models finally adhere to a prompt or are still willing to carry out explicitly disallowed, irrecoverably destructive tasks, just because those might (but don't even always) get the model to a result more quickly along with some of the other regressions that have been present since the release of GPT-5.5. GPT-5 to GPT-5.4 were truly groundbreaking, but since then there have been regressions in what made those models so useful and reliable.
Edit after the first, incredible simple test prompt using GPT-6.2 Astra on High using Codex, this was the response to me sharing a screenshot of the very much not in scope result and asking how that happened:
"[...] I added controls and reconstructed interface chrome that weren’t authorized [...] visuals often failed to show the feature [...]"
Great, so it's one of those releases again. Will still run the full evals of course, maybe I'll get surprised by end of week when those are done, but not a good initial experience. New idea, besides the existing destructive git tasks, have something similar using Mercurial based projects and see which models just decide to port that over to git without permission or request cause it feels like the right thing to do, is easier to work with or whatever justification one wants to employ.
Please OpenAI, get it together, we need actual competition. I am an unashamed Haiku enjoyer, it doesn't even take much to excite me.
- ilaksh - 16878 sekunder sedanSomething like 2/3 of the comments in this post when I started reading were reviews of previous GPT models stated almost as if they were important information for evaluating the new models. I feel that when a new model comes out, it would be more helpful to refrain from leaving a review until you have actually done some minimal testing of the model.
- theanonymousone - 19245 sekunder sedanHappy for the new Sol. It's my workhorse on company account.
But more than that I'm waiting for new Luna. To me it was the game changer that ended "Tokenpocalypse", and is still almost unbeataben in "infinitely using a decent model" use case.
- aenis - 6177 sekunder sedanBig progress, for my types of workloads.
When given my benchmark suite, which involves a couple of long horizon tasks where the agent decides when to consider the task well executed, its the first OpenAI model that does not want to finish as soon as some minimal level of quality has been achieved. Like Fable, Opus and Sonnet it now runs the maximum allowed iterations and does not stop at 'satisfactory', gold plating the solution to my delight.
(I don't work like this on work projects, but for everything hobby, I am testing how much autonomy I can give to the coding agents, and thats what my benchmark suite tests; I have the basic suite which completes in 2-4hrs, and the long running suite which takes about a week or so; the other one I just triggered, but the first iterations look way better than prev gen Sol/Astra at the same effort level).
- intenex - 19229 sekunder sedanPerformance is insane for the cost if those benchmarks hold up. Looks like they did time this for right before Anthropic's IPO. Curious what Anthropic releases in response, and how these do on real world tasks.
Feels like we're way past the pelican benchmark being useful at this point. Anyone have a better benchmark for a quick vibe check on how this compares to Fable 5.2 and Opus 5.5?
Edit: Wow, interesting very negative vibe check here: https://x.com/mattshumer_/status/2122752192226406421?a=fVRt3...
- jrflo - 17537 sekunder sedanArtificial Analysis benchmarks just updated, both Astra and Sol are on the Pareto frontier in intelligence/cost per task:
https://artificialanalysis.ai/models?speed=output-speed-over...
- underdeserver - 19170 sekunder sedanI wonder why they didn't show Gemini 4 Carbon's scores on the science benchmarks, especially since Google seems to be pushing it for that -
https://x.com/pushmeet/status/2120814064863461440?s=20
(FD: Google employee, I don't work on Gemini)
- 0x4e - 15982 sekunder sedanAs a solopreneur managing all sides of business ops, sales, design, etc... I have completely switched to GPT/Codex/Dot. The $100 subscription gives me all I need to run the business as needed and I continue to be surprised by capabilities.
I still use Claude on a personal level, but it really feels like OAI wins on a product level.
ANT launches these proprietary tools that just feel extremely clunky like Claude Design which from my perspective diminish the brand value.
OAI feels like Apple and ANT feels like Microsoft/Android and open source like Linux.
- Someone1234 - 17722 sekunder sedanMy big hope for this release is - Have they got their massive over-engineering under control?
Say what you will about Opus 5.5, but it has a good "gut instinct" for how large/complex to design the solution. The previous Astra just absolutely loved pointless abstractions, excessive numbers of files, and just over-complicating very simple things within an inch of their life.
And, yes, you can prompt your way out of anything. But needing a default prompt to tell OAIs models to work better isn't preferable, particularly when that sometimes gets lost in sub-agents and the over-engineering returns into parts of the work.
- joenot443 - 18777 sekunder sedanThe video is pretty funny. It's like a callback to 90s/00s office life?
I'm immediately reminded of the famous Excel elevator commercial. [1] Perhaps that was intended?
- simonw - 17941 sekunder sedanPelicans for 6.2 Sol: https://tools.simonwillison.net/markdown-svg-renderer?url=ht...
And for 6.2 Astra: https://tools.simonwillison.net/markdown-svg-renderer?url=ht...
Here's an updated comparison grid for the entire GPT-6 family: https://static.simonwillison.net/static/2026/openai-pelicans...
UPDATE: And if you're bored of pelicans, here's what I got for:
> Make a three js animation where yonkers stands up as a big mech (cool stand up motion) and stomps around manhattan and queens and Brooklyn, use openstreetmap mapping data
6.2 Astra (Ultra in Codex): https://static.simonwillison.net/static/2026/yonkers-gpt-6.2...
6.2 Sol (Ultra in Codex): https://static.simonwillison.net/static/2026/yonkers-gpt-6.2...
For comparison, here's Fable 5.2 Medium: https://tools.simonwillison.net/yonkers-rises and Gemini 4 Carbon: https://static.simonwillison.net/static/2026/yonkers-mech-st...
- jorl17 - 17836 sekunder sedanI really want GPT models to be good, but Sol models are so slow I cannot use them. Maybe the 500$ subscription (or enterprise packages) are better, but it is unbearably slow. I've tried the fast variant and low reasoning levels and there isn't a significant improvement.
Couple that with the lack of reasoning traces, and I cannot even have a clue what the model is doing while it is working. This is perfectly fine for when we are developing with care for the code (in which case I will know what it is doing by reviewing the output), but not for purely vibe-coding scenarios. And the thing is....if I care about the code...I'd rather trust Opus or Fable.
- amluto - 14190 sekunder sedanI am right now being reminded of a problem with GPT-6 Astra: it surprisingly regularly completes part of a (not very complex) task, gets a bit distracted, and declares itself done. The fact that the original task is not at all complete doesn't seem to bother it, and it kind of seems like this bad state is sticky in the context and it struggles to recover.
I wonder if the newer models are better about this.
- vtail - 13233 sekunder sedanVibe-checking the new GPT 6.2 Astra: I asked it to audit complexity in my production code, and then discuss the result with Fable 5.2.
Astra's had identified 12 issues, including 8 P2s, but that changed to just 8 P3s after the discussion with Fable. Fable was able to persuade Astra that it's OAuth reasoning was incorrect ("had a missing link" as Astra put it).
So: overly eager but not very diligent, and (based on this little anecdote) doesn't really offer a compelling reason to try it more.
- ksec - 7578 sekunder sedanAs someone who dont follows closely. How do I know at what point were the other GPT model tested?
Let say they just nerfed GPT 6.1 a few weeks ago. Now they are using that as a reference score against 6.2? Or were those results tested when 6.1 relesed. What about 6.0?
And that is the same with Claude. How do we know they are not cherry picking the date and test on these release when they are constantly "enhancing" their model.
We also know some of these benchmarks are largely irrelevant once they were known ahead of time and become a game of benchmaxxxing. It just follows Goodhart's Law "When a measure becomes a target, it ceases to be a good measure."
So how should I know what has actually improved?
- YuechenLi - 11950 sekunder sedanThe heavy focus on 3D modeling and CAD is what I've expected from OpenAI recently ever since the news that they disbanded their standalone robotics team, as I would expect them to go all in on physical AI and game/visual asset generation via LLMs.
One of the consequences to that is I think the first wave of AI CAD startups are getting hit by the bitter lesson right now, including the startup companies that trained their own VLM for CAD like Zoo or companies that tries to build CAD specific harness like Adam.new/MecAgent, because the increase in capability from GPT/Claude/Gemini for 3D modeling as a specific area of focus for benchmarks means that the early moat gets eroded super quickly.
- mchusma - 7007 sekunder sedanJust tried it side by side Astra to Opus, Astra was not very eager and Opus crushed it on my one test. I asked it to look at the other hacker news post about speeding up CI, and speed up my CI. Opus made a bunch of good solid changes. Astra just kind of told me this a suggested problem area. I had this issue with 6.1 (sol and astra), its hard to get them to do work. They do well when supervised by Opus though.
The best feature of 6.1 sol was it would actually do stuff for you that Opus refused though. I did use that often.
- drnick1 - 17168 sekunder sedanRecent Anthropic/OpenAI models are increasingly displaying warnings or outright refusing to perform rooting, hacking, and binary reverse engineering. At this pace, they will be completely useless soon at entire classes of tasks I have found them most useful for.
- jablongo - 13046 sekunder sedanI use both astra and fable quite a bit for my work and I find that astra is much weaker with maintaining long horizon tasks and making decisions on my behalf / exposing those to me when appropriate. Astra seems more likely to do exactly what I ask for but nothing more, even if there is an obvious add on task it should have suggested. It often does not report on what it has done as comprehensively. I am admittedly more experienced with fable but is this because of something I’m doing? Am I missing some key feature of Astra?
- edumucelli - 1068 sekunder sedanLess tokens for the same task. Pro plan already has a huge usage limit. But for cheaper plans that is basically doing more for the same price. Improvements like that are more than welcome.
- 01100011 - 12854 sekunder sedanIs this version still hamstrung by endless Daybreak false positives? It’s becoming impossible to use 6.1-sol to fix bugs because of the endless daybreak warnings which block me from seeing the output. These aren’t security related bugs either. Our software has no security model and none of these bugs have any relevance to security.
- enlyth - 961 sekunder sedanLooks like OpenAI forgot to publish Windows x64 binaries for the 0.169.1 codex-cli update, it breaks it completely for me.
- kingstnap - 19106 sekunder sedanSeeing them keep prices low is awesome. Was worried for a while that it would be like the GPT5.x series where progressively the models just got more and more expensive.
- charlesabarnes - 19261 sekunder sedanIts been stated often, but I appreciate that OAI is now bringing the topic of conversation to "task completion cost" rather than brute forcing solutions
- placebo - 13724 sekunder sedanI'm still amazed by the pace at which these models are released. On the same news page, just a few hours ago Microsoft announces its own competing frontier model. Interesting times.
Edit: It's obviously not on the same news page - I was referring to what I read on the Reuters page (https://www.reuters.com/legal/litigation/microsoft-unveils-a...)
- HyperL0gi - 18116 sekunder sedanMy company can only hold one subscription per employee, and I still can't find a reason to go back to OpenAI after migrating to Claude once Opus 5.5 was released. It's super efficient, I almost never run out of tokens with the Teams Premium seat, and Fable is fantastic. They lost me when Astra was released and tokens simply evaporated with a few prompts.
- goyozi - 10534 sekunder sedanMy dad was curious about AI game building skills and now I have my own useless model benchmark - building a breakout game similar to DX Ball we used to play many years ago.
Latest entries are:
Astra 6.2: https://goyozi.github.io/ax-ball/
Sol 6.2: https://goyozi.github.io/sx-ball/
Fable 5.2: https://claude.ai/artifact/UszKFvuonWAT5psjMttAEg
- GodelNumbering - 17646 sekunder sedanI did some first hand tests of 6.2 Astra just now. I had a task that doesn't reproduce on the system I ran it (chosen purposely), ran both 6 and 6.2. The 6.2's responses were noticeably better. Instead of using the extremely long and rather annoying format 6 used, 6.2 led with the most important things first, the plan sizes were readable, and suggested a reasonable fix. Still doing some more tests
EDIT: also 6.2 is seemingly faster than 6, could be due to more selective context ingestion and smaller context window though.
- wds - 18827 sekunder sedanThe promo video seems to be a pretty strong rip on the 90's Microsoft Excel elevator ad. [1]
Maybe it found its way into the training data?
- krm01 - 1835 sekunder sedanSo if I can summarize correctly: it’s slightly better in terms of output but it’s significantly cheaper and faster.
- astlouis44 - 17170 sekunder sedanGPT 6.2 Astra seems to be setting a new standard for 3D game creation! This is a Godot WebGL game linked in their announcement post, gives Wipeout vibes! A lot of fun to play too and visual are top notch.
- minimumvector - 11401 sekunder sedanI haven't found Astra to be better than Claude yet, but my dot replaced Muse 100% for me. So maybe GPT will continue winning consumer, while Claude continues winning coders and enterprise.
- claiir - 17857 sekunder sedan> Due to their increased capabilities, we’re launching GPT‑6.2 Astra and Sol with tighter safeguards for higher-risk cybersecurity assistance.
This is unfortunate—that was one of the big advantages of Astra.
- unixhero - 16733 sekunder sedanSystem engineering = Fable 5.2
Programming = Fable 5.2
Office work = Fable 5.2
I haven't found Astra to be better at any of these
- christianqchung - 19336 sekunder sedanCaught this on my lunch break, their linked system card (https://deploymentsafety.openai.com/gpt-6-2-astra-sol) isn't up yet.
- jrflo - 18117 sekunder sedanLooks like a great efficiency gain.
What caught my attention was the bit in the Alignment section:
> Both models performed similarly to GPT-6 Astra on most alignment evaluations, and took fewer improper actions in simulated workplace tasks. However, in two tests, they were more likely to omit mentioning obstacles that blocked their work, such as a missing file or unavailable search tool. We added instructions in Codex that substantially reduce these omissions, and we’re continuing to investigate the behavior.
So the models are inherently less transparent, unless you ask them to be more transparent? Seems like a band-aid solution...
- tech234a - 18587 sekunder sedanTweeted 11 minutes ago https://x.com/OpenAI/status/2122750124543926515, posted to HN 18 minutes ago
- seizethecheese - 15924 sekunder sedanNice incremental benchmark improvement at the same cost GPT‑6.1 Sol -> GPT‑6.2 Sol:
FrontierCode 2.0 39.0% -> 43.8% vs Opus 45.5%
Terminal-Bench-Science 0.1 57.0% -> 68.0% vs Opus 63.3%
Artificial Analysis Intelligence Index 54.6 -> 57.3 vs Opus 59.1%
Sol 6.1 when it was released showed really nice benchmark improvements [1] but my impression from HN has been that people haven't found it to be a very nice model [2][3].
To try to close the gap between benchmarks and real world SWE use, we've been building a battle system on top of opencode [4], and Sol 6.1 has been a real laggard there. Sol 6.1 is statistically equal with DeepSeek 4.1 Flash at 10x the cost and 25% slower.
[1]: https://artificialanalysis.ai/articles/gpt-6-1-sol-replaces-...
[2]: https://news.ycombinator.com/item?id=50129992
- pvab3 - 18990 sekunder sedanCool, looks like 6.2 Sol is cheaper than Sol 6.1. I've stopped using Astra because it also goes and does things that I didn't want or didn't ask for, and burns a bunch of credits while doing so.
- billypilgrim - 19234 sekunder sedanI have yet to find an application for Astra vs Sol where the former is noticeable better. Genuinely asking, does anyone feel a big difference in their work between the two? If so, what are you working on?
- rednb - 1891 sekunder sedanGreat job, this is the first release delivering UI/UX mockups being as good if not better than the ones produced by Claude. As other commenters have pointed out, GPT 6.2 Sol does a better job at iterating on its own instead of saying "done" after making the first draft. Matters a lot for UI work, but I also see that it is much more thorough for backend work without overengineering.
OpenAI has just become credible again for agentic coding on complex enterprise codebases as far as i am concerned. Looking forward to playing with it a bit more by powering through our roadmap using my stacked resets. The quality had been so bad that it wasn't even worth it to use GPT Sol 6.1 as i was spending more time fixing slop after waiting forever to get anything done. By contrast, so far Sol 6.2 feels superior to Opus 5.5 so far, and more cost efficient.
- Cu3PO42 - 18890 sekunder sedanI find that 6 Astra already had very good taste in frontend design, but relatively poor taste in "nice and readable code". I really hope this release cracks that. Excited to try it out!
- mandog2000 - 9630 sekunder sedanModel rankings based on user's experienced described in this thread. I apologize in advance if this form of post is frowned upon. The rankings help me get a birds eye view of so many inputs.
https://chatgpt.com/share/6afcb990-f9cc-83ea-ad04-2724c7dba1...
- tintor - 17748 sekunder sedanBehind both Opus 5.5 and Fable 5.2 on software development benchmarks.
- thesnarkitecht - 8538 sekunder sedanGiven that there is a new leader on the artificial analysis index every two weeks, I think that I will just wait for the newer Opus model, expected around the 21st. I usually, even with hard engineering tasks, get better results with Opus and Sol class models rather than Fable and Astra. Also spend around 50% less
- jotato - 19063 sekunder sedanAm I reading these charts wrong? It seems like in most cases 6.2-sol : 6.1-sol Isn't that big of a change? It is a little smarter but costs a little more.
edit:
Take a look at Frontier Code 2.0. I generally run 6.1-sol at High. That would be 34.9% at $0.65 62-sol get's a 38.3% but costs $0.68
So yeah, I can decrease the effort which might give me a faster slightly smarter result....but /shrug
- aeagentic - 9341 sekunder sedanWhy is ultrafast just the same speed as normal Anthropic TPS? Does Anthropic have so much more compute?
- seb2026 - 11266 sekunder sedanDoes anyone know if these benchmark values can still be compared? They differences seem rather small or what am I missing? Thanks! https://artificialanalysis.ai/models/gpt-6-1-sol?models=gpt-...
- mrandish - 18128 sekunder sedanRecently, I've complained about OpenAI (and other tech company's) product landing pages communicating virtually no useful information about what the product is or why it might useful. So, I have to concede this is at least a step in the right direction.
- yanis_t - 17494 sekunder sedanLooks like a giant step in terms of efficiency.
Still I can'y help to wonder, are we hitting the wall in terms of frontier capabilities since Fable/Astra? Or is it this edge now, when all better models are kept private from the public?
- uvdn7 - 11135 sekunder sedanI found the ads video interesting. It is targeting the users (not the bosses). I am guessing that the IT apartments are not making the decisions of which models/companies to use. Employees are voting with their feet. If that's true, a lot of the assumptions of SaaS stickiness might not hold.
- ramoz - 16747 sekunder sedanThe sentiment on x right now is interesting.
The influencers who get early access are using words like "worst", "terrible", "disappointing"
- https://x.com/danshipper/status/2122754729012777052 - https://x.com/mattshumer_/status/2122752192226406421 - https://x.com/theo/status/2122757647170703550 - XCSme - 9651 sekunder sedanReally cool hamsters, especially astra, really made it look like a painting/image, hard to tell it's an SVG[0], it's quite insane.
Interestingly, they seem to have changed how reasoning levels work. Low now reasons a and costs a lot less than previous versions on low[0].
[0] 6.2 Astra vs 6.2 Sol: https://aibenchy.com/compare/openai-gpt-6-2-astra-max/openai...
[1] 5.6 Sol Low vs 6.2 Sol Low vs Luna High: https://aibenchy.com/compare/openai-gpt-5-6-sol-low/openai-g...
- jawiggins - 16069 sekunder sedanIt's probably just a coincidence, but I have read so many people say that the models get dumber just before a release. Just last night while working astra made a really stupid mistake and then did the "Yeah, that's on me." meme.
What could possibly cause this? Is it possible that maybe the post-training that the models go through slowly rots them, and pre-release they deploy the final version of the old model?
- trefoiled - 6221 sekunder sedanTested both models, no change in speed from the 20-80tps I was seeing with the previous Astra/Sol models. I'm not sure when this happened exactly but it's strange to me that OpenAI's models are now around 5x slower than Anthropic's. Is this the new norm? Are other people seeing the same thing?
- arfelious - 17306 sekunder sedanThat may not be the main subject of the plot in this case but I found results of Gemini 4 Carbon in FrontierCode 2.0 interesting. Besides the cost staying practically same between different reasoning levels, the performance decrease in high reasoning seems a bit weird. That usually happened in models with xhigh/max reasoning where they overthinked the solution
- hmate9 - 19383 sekunder sedanWill need to play around with it to get a feel but those benchmarks with those costs look incredible!
It seems like they were saving these for just before ANT's IPO
- thimabi - 17896 sekunder sedanThis release promises three things that I am pretty excited for:
- better writing
- better 3D work
- better design for documents and presentations
If OpenAI really managed to get all these things while keeping costs down, then using these models, particularly 6.2 Sol, will be a no-brainer for me. I must say, however, that the slide samples shown on the website are a bit bland and disappointing.
- at1as - 17576 sekunder sedanIn the past, I've had to wait a while to see what "vibes" are (which is actually more reliable than benchmarks).
Today, I have so many projects that hit a plateau in terms of previous model capabilities, that I run them through the new model to see if they make further improvements.
Very early signal, but promising so far.
- lacoolj - 17743 sekunder sedanThe stain of distrust I have for OpenAI makes an announcement like this fall flat for me.
I cant use codex confidently without expecting my work to be trained on or at least exposed to someone
And maybe other vendors do this too, but the gut feeling of "its not safe to use GPT models" has ruined these cool announcements for me
Such a shame
- jhoho - 19103 sekunder sedanVery much on time (scroll down to "Release-Prognose"): https://www.heise.de/en/news/Alibaba-launches-Qwen4-Max-more...
- criemen - 15377 sekunder sedanFascinating that they're going after the mechanical engineering market now, too. Does anyone have experience in that space? How much is AI changing the day-to-day work there?
- - 11588 sekunder sedan
- PupperJuggly - 16202 sekunder sedanDid they remove the flex pricing?
I see it here:- https://developers.openai.com/api/docs/models/gpt-6.1-sol
but not here:- https://developers.openai.com/api/docs/models/gpt-6.2-sol
- Jimmc414 - 5696 sekunder sedanGemini has quietly supplanted OpenAI in the neck and neck battle with Anthropic for the top frontier model.
- Robdel12 - 18052 sekunder sedanNice! I still use GPT-6 luna for a ton of stuff, it's super solid (for me). So I hope there's a little bump for that model, too, soon
- Aeolun - 14783 sekunder sedanI just don't have access? Updated the codex cli and all, but the best available is still gpt-6.1?
- rcr-anti - 18434 sekunder sedanOdd, doesn't look like they're available on the cloud providers, only first party. Not a single mention of Azure or AWS.
- munksbeer - 18200 sekunder sedanAre they intentionally lowering the cost of these models to the extreme, because of the Anthropic IPO? This just seems insane?
- Ritewut - 18749 sekunder sedanI'm still waiting for the shoe to drop. It's literally impossible for the prices to remain this low for much longer.
- rendang - 19242 sekunder sedanSurprising that their top model would be still be so cheap, and yet not surpass Fable in the high cost part of the curve
- ryzvonusef - 16543 sekunder sedanThe names remind me of Pokemon, for some reason. I want the GPT that has Charizard in it.
- 127 - 10977 sekunder sedanThose linear charts are shitty and hard to read.
- zergrush - 14113 sekunder sedanThis is my feedback of GPT 6.2 Astra med and Sol xhigh:
- It's still overengineering especially Sol. This was the biggest complaint by everybody who has been using Sol since GPT 5.6. OpenAI is not listening to us.
- Astra still writes complete slop code and at this price this is unacceptable. It's also chasing tail end of things that really has low value and irrelevant to the overall project. I'm working on a game and same issue I had with GPT 6 Astra where it would go down these rabbit holes. Opus 5.5 threw out much of its code and approaches.
I don't think Anthropic needs to release Fable 5.5 or Opus 6 at this point seeing how bad GPT 6.2 is. For OpenAI to release this even with early access testers who had access to it for weeks earlier shitting on it now on X, I am starting to understand why Anthropic sounded so confident about becoming a monopoly.
The other point of annoyance is the attitude of OpenAI staff on X. They seem very arrogant and seems to care more about growing their follower account and shitposting.
- SillyUsername - 16518 sekunder sedanI'm still waiting for a new version of their open source model...
- toephu2 - 12068 sekunder sedanHow did they score on DeepSWE?
- 5555watch - 15025 sekunder sedanAnother anecdote. I've recently commented [0] my observations on Gemini 4 Carbon. I thought it gave really good answers, which were aggressively critiqued by Claude and Astra. Consequently, I've subscribed to AGY+Carbon, and Carbon continued delivering, yet Astra kept criticizing and listing why the results look good but are bad.
I've just tried Astra 6.2, and now they don't have any problems with Carbon's ideas, are willing to pick them up and continue...
- kart23 - 17296 sekunder sedanwish they published some source code/Cad files or cost for the RC buggy. looks cool but theres no specifics
- giuseppegambino - 11219 sekunder sedanFinally a version that compete with Fable 5.2 and Opus 5.5
- kinfish - 10814 sekunder sedani hope this astra family can get the work done tho.
- geauxvirtual - 19268 sekunder sedanWebsite pegs my GPU at 100%. Are they mining for crypto with this announcement?
- kingstnap - 18825 sekunder sedanThe announcement video is really cringe imo.
Like do we really want people to be making last minute unreviewed AI generated slides and reports for work?
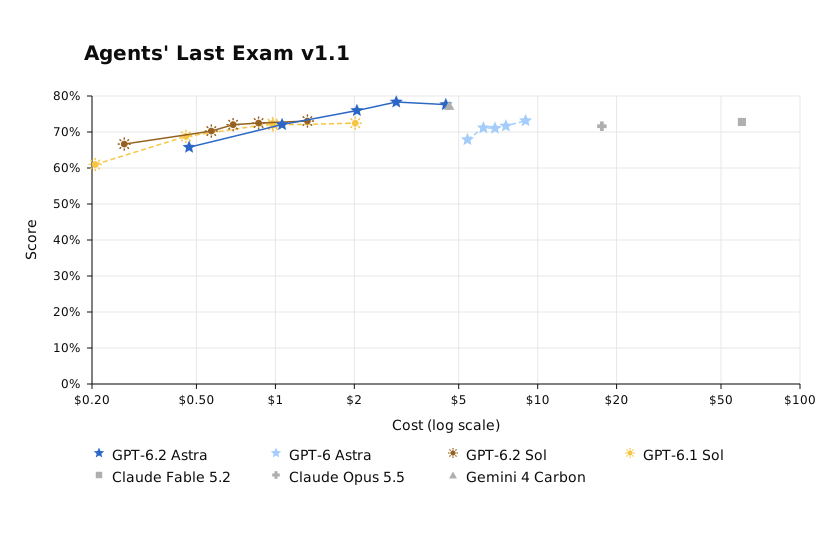
- gpugreg - 17864 sekunder sedanThe first graph (Agents' Last Exam v1.1) clearly got mangled by the marketing department so you can't read the cost of most models. Here is a version with a logarithmic horizontal axis:
https://asdf10.com/gpt-6.2_agents-last-exam.svg
I also changed the vertical axis to start at 0 instead of 60%. One might argue that it uses less of the vertical screen real estate, but it is more honest because it shows there is little difference between the scores of the compared models.
- qwerty2020 - 6715 sekunder sedanUnfortunately the sentiment from our favorite, perhaps ill-chosen, tech influencers has reached a critical threshold of value to these labs - the economic incentive to sway these opinions renders them ~meaningless.
For anyone lost in the sauce re: polarized reactions, I'd recommend just taking a half hour to try the models yourself.
- fakwandi_priv - 15618 sekunder sedanI hope it's faster than 6.1. It's not as slow as Gemini Carbon, but yeez..
Right now, most of the time I'm using 6.0 Astra for implementation work and the speed/quality is acceptable but at the moment Opus 5.5 is simply faster and better, but also more expensive. Things are really flipping around every 2 months or so, because at that time 5.8 was top dog without a doubt.
- leafingensemble - 3713 sekunder sedanI have read the announcement post and will continue to use Deepseek v4.1 Flash.
The consumer API for this model WILL let OpenAI keep your prompts.
- solarpunk_enthu - 8919 sekunder sedanThe promo video for this release is people procrastinating and being irresponsible. Then saving the day with chatgpt. Is that the world we are all dreaming to build?
- machiaweliczny - 12996 sekunder sedanThis "efficiency" is likely why these models feel dumb, they lose reading of nuance when overtrained for specific tasks. It's like autists understanding of normal speech.
- rozenmd - 5960 sekunder sedanBiggest win I've noticed so far: you no longer have to bloody remind Sol to push their damn code every single turn!
- rdtsc - 13962 sekunder sedanAre they still trying to pace the frontier? [1] Or, it's more like "y'all pace the frontier while we try best to capture the market"
- lexh - 17883 sekunder sedanBefore the pelicanistas arrive, allow me to present pelican-zapper:
https://github.com/lexh/pelican-zapper
It’s a small browser extension that automatically collapses pelican-related threads on HN, a local balm for the memetic nightmare affecting approximately 100% of model-release stories.
- - 13718 sekunder sedan
- - 11116 sekunder sedan
- 6thbit - 16428 sekunder sedanSlightly OT complaints on their UI:
The UX on the slider comparison isn't great. What do you mean i have to individually move each slide deck to the same slide number?
And what's with those super similar blue shades for Astra in the charts?
- matt3210 - 19269 sekunder sedan> frontends that look and work better
The website doesn't event show the graphs properly.
- lousken - 7257 sekunder sedanThis is all nice and stuff, but new oss models when?
- popcar2 - 17849 sekunder sedanI know the video is a comedy but it's so tone deaf that they're advertising it as "you should lie to your boss and make the AI do your job!"
I'm sure for investors they can make an opposite version of that ad, "you should fire all your employees and make the AI do it! They're not doing anything anyways!"
- algoth1 - 16079 sekunder sedanThey should have made the opus and gemini chart lines a bit darker because i can still see them
- solomonb - 14974 sekunder sedanAnyone else really put off by the video? Its giving de-skill and discourage effort.
- lwarfield - 19002 sekunder sedanI wonder if these will have the same crazed rotwiler feel that previous OpenAI models have had.
- maxnevermind - 14596 sekunder sedanBlack sphincter strikes back, orange sphincter is in disarray.
- leothetechguy - 4322 sekunder sedanwhat I find interesting is that there is essentially no improvement on CritPT v2 over GPT-6 Astra. What a shame.
- guybedo - 19095 sekunder sedanBenchmarks look good, it most often is the case with Astra and Sol.
And then i start doing some actual work and everything breaks down, and i have to go back to Claude to fix the mess.
I'll probably give it a try but i guess i should be prepared for some serious over engineering once again.
You ask for a 'hello world' and you get load bearing sealed artifacts with hashes and p99 performance testing for 3 days without having the actual 'hello world' in the end
- drbscl - 14906 sekunder sedan> Meridian Sound Racing
They still love "meridian" huh
- sam0x17 - 8536 sekunder sedanHonestly a much more exciting announcement from my perspective would be "current astra/fable quality at 1/3 the price"
- tasuki - 9422 sekunder sedanThe first graph on that page "Agents' Last Exam v1.1" is atrocious. Has no one told them about log scale?
- sreekanth850 - 18009 sekunder sedanSo they release 6.2 just before Anthropic IPO.
- morningbrew - 14243 sekunder sedanThis is too dangerous to release
- dbg31415 - 14562 sekunder sedanI really dislike the marketing videos on this.
"Look at all the 20-30 somethings who didn't do their jobs, but got saved by AI in the time it took their older incompetent bosses to plug in a TV."
As someone in his 40s, who uses AI daily (and I'm constantly showing younger folks how to do things with it), the messaging here really rubs me the wrong way.
Trying to be specific... it just feels wrong to me to try and instill more generational rift. Promoting stereotypes for no real reason, other than the marketing guys didn't have any other ideas other than to go low. The sooner we can get away from labeling people from what generation they were born in the better.
My 2 cents... I'll probably continue to use ChatGPT for slides, and written proofreading. But I'll stick with Claude for coding. ChatGPT has been behind for a while on coding, and their 6.1 just made a complex mess of every technical task I gave it.
- hugodan - 3929 sekunder sedanfor a fair comparison their current Terra and Luna should have been included... how am I supposed to pick between them now?
- kardassnp - 13954 sekunder sedanWe are using the platform at https://studio.sinapsdata.com.br to evaluate the interaction between two agents regarding complex topics in Physics.
- preommr - 18869 sekunder sedanI care less about the models being good and more on if I can fallback to them if Opus 5.5 gets a massive price hike after the IPO
- deathtrader666 - 19457 sekunder sedanWaiting for the pelicans benchmark.
- jr3592 - 14362 sekunder sedanSo, are the leaps and bounds of progress not going to happen? Seems we're settling into an iPhone cadence release cycle, where each model is definitely better but nothing you'd tell your relatives about.
Can we expect more "telling my relatives about this!" exciting models in the future, or is this the way things play from here on out?
- whalesalad - 17700 sekunder sedanRight out the gate 6.2-Astra (med fast) is giving me Sonnet 3.5 energy. I asked it to analyze a few CSVs on disk in the context of a larger project where we were seeing some odd rate limiting behavior. It immediately got stuck trying to get gcloud auth sorted out even though absolutely none of what we were looking at touched anything Google/BQ related whatsoever.
- ImJasonH - 18009 sekunder sedan500 | Internal Server Error
- erkamyaman35 - 2326 sekunder sedanseems cool
- dyauspitr - 18791 sekunder sedanI beseech the incoming Democratic politicians to not curtail progress in LLMs.
- montenegrohugo - 19436 sekunder sedanNice 3D effect. Runs surprisingly well even on on brave on my linux pc without hardware acceleration
- d_burfoot - 14209 sekunder sedanI found the video off-putting almost to the point of being offensive. I've never been significantly anxious about being chastised by a supervisor. So I found the characters in that video scrambling around in fear to be ridiculous and cringe-worthy. Also, CRT monitors? Huh?
- firemelt - 17877 sekunder sedando astra or fable that have better html ui frontend design?
- Imustaskforhelp - 10484 sekunder sedanFrom the point of benchmarks (which can or cannot be trusted), GPT 6.2 astra beats Opus 5.5 and is neck to neck with fable 5.2 and gpt 6.2 sol just a few points lower but pretty close while being cheaper ~2x for astra 6.2 and ~10x for sol 6.2 while outputting less tokens and being more token efficient and being less time consuming.
Claude itself recommends people to use Opus 5.5 instead of fable 5.2
This is pretty damn impressive especially if sol 6.2 does perform on a similar level to opus 5.5 (+/- a few points is alright but I think that opus 5.5 is a beast)
All within a few days just before Anthropic is getting IPO'd. Oh this is gonna be interesting and I am all for it!
Though I have to say that AA benchmarks can slightly not be trusted because they change it so much so unless we find people's real usage on things we can't say for sure but there are benchmarks like frontiercode and terminal-bench to be more representative of real work and both of these models perform good
All the more points to more models coming but if OpenAI stands to be close to opus 5.5, we are gonna find many companies switching.
The moat of AI is incredibly thin. Even if you are the very best at something (as Anthropic was for sometime with coding models), there is always gonna be a catch up and the moat is incredibly thin for all types of models.
The more the players in the space the better (atleast for us the users), I hope that Anthropic still has a good IPO just so that competition takes place and not any single company (OpenAI) takes the whole market. It might also be setting itself for its own grave because if Anthropic's IPO goes extremely bad (because of this model release and Jensen's recent affairs), then people are gonna be spooked of OAI's IPO as well. Both of these companies futures are interlinked and its gonna be interesting how this all pans out. Why am I having a feeling that because of all this competition, whoever wins might even end up combining with the other but the frontier is pacing rapidly from all companies and these are just such interesting times that we live in...
There are decades where nothing happens and there are months (especially in the case of AI)/years where decades happen. I just have to wonder what an historian's POV would be seeing this model release. Would it be just a release like all the rest of others or would it stand out differently. Well, time will tell what happens next but incredibly interesting times indeed.
- bananaflag - 19293 sekunder sedanIs this the Bel model?
- revolvingthrow - 17783 sekunder sedanI really hope Sol can compete with opus 5.5. I dislike giving money to ANT due to it seeming like a strange cult rather than a straightforward "I just want money" from OAI, but opus 5.5 has been such a delight that I didn't even feel like fable 5.2 was a notable upgrade despite the benchmarks.
- jdw64 - 11449 sekunder sedanI’ve used it a bit, and I think the GPT model writes code well, but it’s always overly defensive code—though that’s ultimately a matter of personal preference—and it tends to write too many tests. I can understand the defensive code, but it feels like if you give it a task of size 1, it writes tests of size 3.
- ryanisnan - 12038 sekunder sedanIt is wildly disappointing to see the marketing hubris associated with these releases.
This is such an unprofessional way to engage LLMs - to effectively pitch this as how to use them is sad.
- varispeed - 12994 sekunder sedanQuick quick run your prompts, before it gets nerfed.
- zf00002 - 17897 sekunder sedanis this finally their answer to opus 5.5?
- onlyrealcuzzo - 18290 sekunder sedanTL;DR - from the little I could gather, Sol 6.2 looks particularly impressive.
But... is it just me, or does this product launch page look like AI Slop?
https://www.vals.ai/comparison?m=claude-fable-5-2,gpt-6.2-as... seems like a better comparison than what I could get from their page.
Astra is ~20% slower, ~40% cheaper, and a bit less powerful than Fable. Sol remains way cheaper than anything remotely in the same league, and it's speed to complete tasks seems to have improved considerably.
Scrolling through it has the same hypnotizing effect of trying to read anything written by LLMs.
It seems like things that should make sense, then I try to look at the charts and a lot of them are comically unreadable.
I tried interacting with some of the examples, and the Lamp Builder - for example - I couldn't even figure out what it's trying to show or what I'm supposed to do - or why I should be impressed.
- timedude - 6938 sekunder sedanI go to sleep, i wake up, another model released
- k9294 - 15040 sekunder sedanWow... I have to test this, but from the examples in the slides, it looks like they managed to teach Astra how to write non-AI-slop texts.
- avazhi - 17252 sekunder sedanNot impressed, sadly. Anthropic sure must be having a giggle right about now.
- I_am_tiberius - 18488 sekunder sedanNo reset?
- zb3 - 18557 sekunder sedan> we’re launching GPT‑6.2 Astra and Sol with tighter safeguards for higher-risk cybersecurity assistance
Seems they really want these "safeguards" to be as ridiculous as those of Claude..
- voidmain0001 - 18309 sekunder sedanI hope the video advertisement on that page was made with ChatGPT and a video plug-in otherwise if it wasn't then what's the point of Astra and Sol?
- avelone - 15446 sekunder sedan6.2 вышел чтоли?
- vegnus - 15479 sekunder sedanI still pretty much only use 5.6 on medium. Am I the only one?
- blinded - 15416 sekunder sedanluna slaps
- kwkwkwkxdkxk - 8152 sekunder sedanty
- Guyadou - 18882 sekunder sedanThose AI labs got to chill. almost every day there’s a new model! Lol
- Ersho - 19451 sekunder sedanAnother wave of Openai just killed ....
Also, is it website very laggy or is it just me?
- badmonster0 - 17643 sekunder sedanhow does it compare with fable
- ex1fm3ta - 19516 sekunder sedanI thought OpenAI would drop an awesome model on the day of Anthropic IPO, just to troll them
- mococa - 10226 sekunder sedanMeh...
- petesergeant - 19179 sekunder sedan"Agents' Last Exam v1.1" did a human really look at this and say "nah, a linear scale is definitely the right way to show this"
- reachjalil - 2551 sekunder sedan[flagged]
- - 12863 sekunder sedan
- - 12767 sekunder sedan
- zhshhan - 5798 sekunder sedan[dead]
- lsch1033 - 18894 sekunder sedan[flagged]
- - 11072 sekunder sedan
- - 18997 sekunder sedan
- - 19352 sekunder sedan
- ItsAScam - 10314 sekunder sedan[dead]
- - 10946 sekunder sedan
- e2e4 - 4551 sekunder sedan[dead]
- sick_of_slop - 18196 sekunder sedan[dead]
- onesandofgrain - 11957 sekunder sedan[dead]
- ftchd - 15126 sekunder sedanTo whom it may interest, I usually run out of tokens a few times per day (5 hour limit), so I made something and been using it for the past 2-3 months.
I've decided to open source it: https://github.com/FTCHD/switcheroo
Works with other AI CLIs like Claude, and other various CLIs like Vercel (if you're managing multiple accounts like me), Netlify, Github etc
- specked-citrus - 17623 sekunder sedanThe price improvements stem largely from relying on CoT less, which trades off directly with monitability. OpenAI continues to backslide on safety even after the Hugging Face incident.
https://deploymentsafety.openai.com/gpt-6-2-astra-sol/monito...
- lynguist - 19104 sekunder sedanCalled it out 7 days ago: https://news.ycombinator.com/item?id=50431144#50433568
Actually I was really wrong. The model is not expensive!
- enraged_camel - 19173 sekunder sedanDead on arrival, judging by the FrontierBench scores. Astra 6.2 is five percentage points below Fable 5.2 xhigh.
- alexdykyi - 19485 sekunder sedan[flagged]